 1 hour ago
6
Follow us
Add us as a preferred source on Google
Subscribe to our newsletter
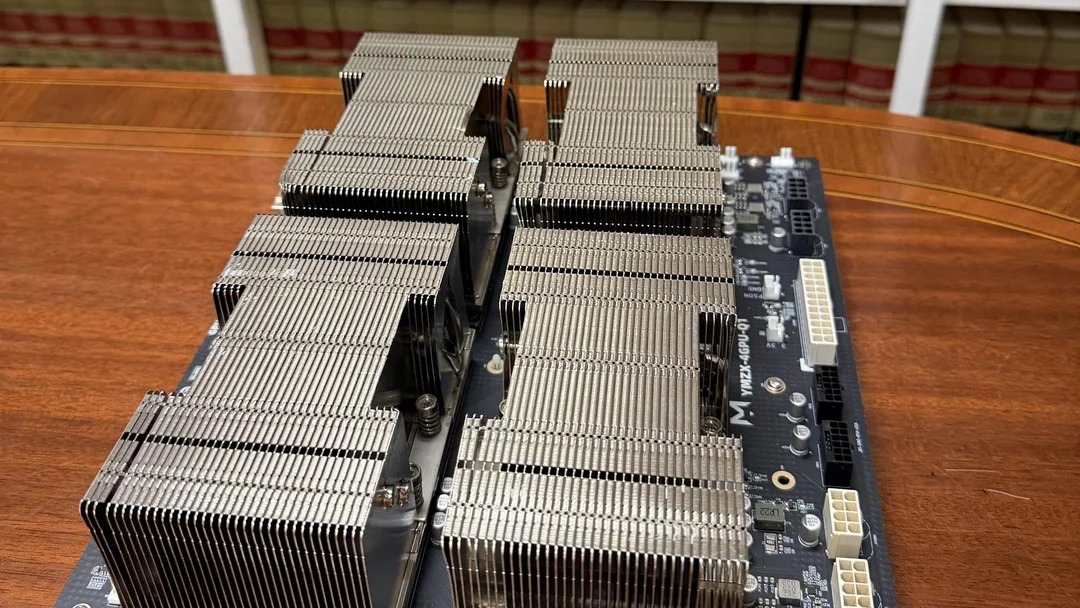
A lawyer posted on Reddit about their private AI server built from eight used 2018-era Nvidia Tesla V100 data center GPUs so case files never have to leave the office. With two 4-card SXM2 NVLink boards, four PEX switches, and SlimSAS cables everywhere — plus one burnt power connector — the builder now runs the open DeepSeek V4.1 Flash model with every expert in GPU memory, at up to 215 tokens per second. The four-GPU boards cost about $2,400 apiece when the builder bought them.
The eight Tesla V100-SXM2-32GB cards, each with 32GB of HBM2 at 900 GB/s, plug into SXM2, Nvidia’s mezzanine socket for data center GPUs, rather than PCIe slots, and are split across two baseboards. Inside each board, all four cards are NVLinked — NVLink is Nvidia’s direct GPU-to-GPU link — for 128GB per board, but the two boards only communicate over PCIe. Each board connects to the host through two PEX (PLX) switch cards over SlimSAS cables, four switches in all, with each switch handling two GPUs at PCIe 3.0 x8 speeds over its own x16 uplink.
The given prices are already in the past, though: used V100 SXM2 32GB cards are now listed on eBay for about $900, more than double the roughly $400 apiece from the post, and listings suggest prices are still climbing. The system also already has some other necessary components: a Gigabyte Threadripper Pro motherboard with a 12-core 3945WX CPU to match, 8x 32GB DDR4 RDIMM, one NUMA node, and two PSUs, 2,800 W in total, are on separate regular office circuits. This is a real-world case for used data center hardware as a cheap route to getting lots of fast VRAM together in one place.
The server is currently in daily use for first-pass work on case files: it reads a folder of records, pulls out facts, dates, and numbers, summarizes them, and takes a first swing at routine drafting. “Nothing goes out the door without a real review,” which is a good human-in-the-loop policy in general. It also helps ensure privacy for cases where client files can’t be sent to a cloud or frontier model. RAG databases and tool calls are wired in; the operator can drive the system through a Discord-style interface over SSH, in this case from a Windows PC. For now, it handles only one request at a time.
DeepSeek V4.1 Flash is compressed to mostly 2 bits here, and its weights still total 248.8GB. The model’s “experts,” the parts that do most of the work for each word, live entirely in GPU memory, while about 110GB of lookup tables, called Engram tables, stay in the system’s regular RAM. Fetching from RAM costs about 0.12 milliseconds per step, which the builder says barely affects the speed numbers.
The first half of the model’s layers (0–19) runs on the first SXM2 board and the second half (20–39) on the second. Each board handles its heavy traffic over its own NVLink, so only one hand-off per step has to cross the slower PCIe link between the boards. In an earlier post, the builder found that splitting every layer across all eight cards made speeds “fall off a cliff” because of that PCIe hop.
Performance is surprisingly good for a model this size. Code comes out fastest, at up to 215 tokens per second, because a small draft model built into DeepSeek guesses five tokens ahead, and code is easy to guess. Legal writing, which is what the server is for, runs at up to 118 tokens per second.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
Long documents take longer to get going: the model reads prompts at about 2,200 tokens per second, so at 128K tokens, the first token arrives after about a minute. It can accept up to 524K tokens of context. Three days before the post, the same model on four of these cards managed just 36–38 tokens per second. The jump came with the second board, which could presumably double performance under ideal circumstances, and the builder credits custom kernels and prefill work for the rest. See the table for the full breakdown.
Swipe to scroll horizontally
1K tokens |
1.2 seconds |
215 |
118 |
32K tokens |
17.2 seconds |
200 |
117 |
128K tokens |
59.2 seconds |
183 |
111 |
256K tokens |
118.7 seconds |
160 |
103 |
Builder’s measurements, Nov. 5; greedy decoding, 1,024 tokens out, mean of two runs.
It wasn’t as simple as hooking everything up and turning on the power. The host reset itself twice with a fatal PCIe error on the link to one GPU board, both times with a higher power limit and uncapped GPU clocks. In this state, the cards drew 192–232 W, past the 180 W limit. The best guess, although “not proven,” is that a board stops responding during load spikes.
The resets stopped after the builder capped the clocks and removed one board whose power connector had a burn mark; “Check your connectors, people.” Each card is now capped at 150 W, half of its 300 W rating, with the graphics clock capped at 1522 MHz. A 200 W cap brought no appreciable performance gains, according to tests.
The system memory hit uncorrected ECC errors, too, which went away after the builder dropped the RAM from DDR4-3200 to DDR4-2666. One GPU was connected at x4 instead of x8 at last check, and the builder plans to reseat it; one commenter traced the same kind of problem on their own V100 to a bad cable.
The pain was worth the payoff as an estimated 50–60% of the lawyer’s existing LLM workflows can now run on the box instead of frontier models. Helping bridge the gap is a second DeepSeek server on two DGX Sparks, where the two systems hand work off to each other. The setup does appear to save money, at least when compared to API pricing, although the builder says it’s not really faster. However, it will protect client data “once it is self contained, which is the goal.”
The builder added that the V100 box might also get a 240 V circuit. Beyond power, the system is also on borrowed time with the Nvidia R580 driver branch, which is the last to support Volta. For now, the lawyer admits that it’s mostly a hobby, but in the future it may be a business idea. The next step is to handle two or three requests at once, something built and checked on a test system but not yet on the server.
Follow Tom’s Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.


 English (US) ·